Access Chutes AI's Private Models on the SayGM Gateway
Chutes AI’s confidential, open-weight models are available through the SayGM gateway, using the same API key as Claude, GPT and Gemini. See how two Bittensor subnets keep your prompts sealed from request to response.
BSBrittany Seales· Marketing5 min read
On this page
Chutes AI is one of the model providers powering the SayGM gateway, giving you access to its confidential, open-weight models with the same API key you already use for Claude, GPT and Gemini. No separate Chutes account, no extra integration.
It's also a partnership between two Bittensor subnets. Chutes (Subnet 64) serves the models, while SayGM (Subnet 28) handles the routing, billing and privacy around them.
This post covers what Chutes brings to the gateway, how a Chutes request actually travels from your app to the model, which privacy tier those models sit in, and how to choose Chutes as your provider when you want it.
Table of Contents
- What Is Chutes AI?
- How Do Chutes Models Reach the SayGM Gateway?
- Which Privacy Tier Do Chutes Models Sit In?
- Choosing Chutes as Your Provider
- Common Questions
- Get Started
What Is Chutes AI?
Chutes is a serverless inference platform built on Bittensor Subnet 64. It hosts LLMs alongside image, video, speech and embedding models, serves them through an OpenAI-compatible API, and has a reputation for getting newly released open-weight models live quickly. By early 2026 it was processing around 120 billion tokens a day and ranked as the top provider on OpenRouter, according to TAO Media's investor guide to Chutes.
For Bittensor builders, the more interesting part is what this partnership represents. Value moves between the two subnets through real usage rather than through a single company in the middle. That's subnets acting as infrastructure for each other, which is the version of Bittensor most builders signed up for.
How Do Chutes Models Reach the SayGM Gateway?
SayGM keeps a whitelist of approved upstream providers, and independent inference providers do the work of routing traffic to them. Chutes is one of those whitelisted providers.
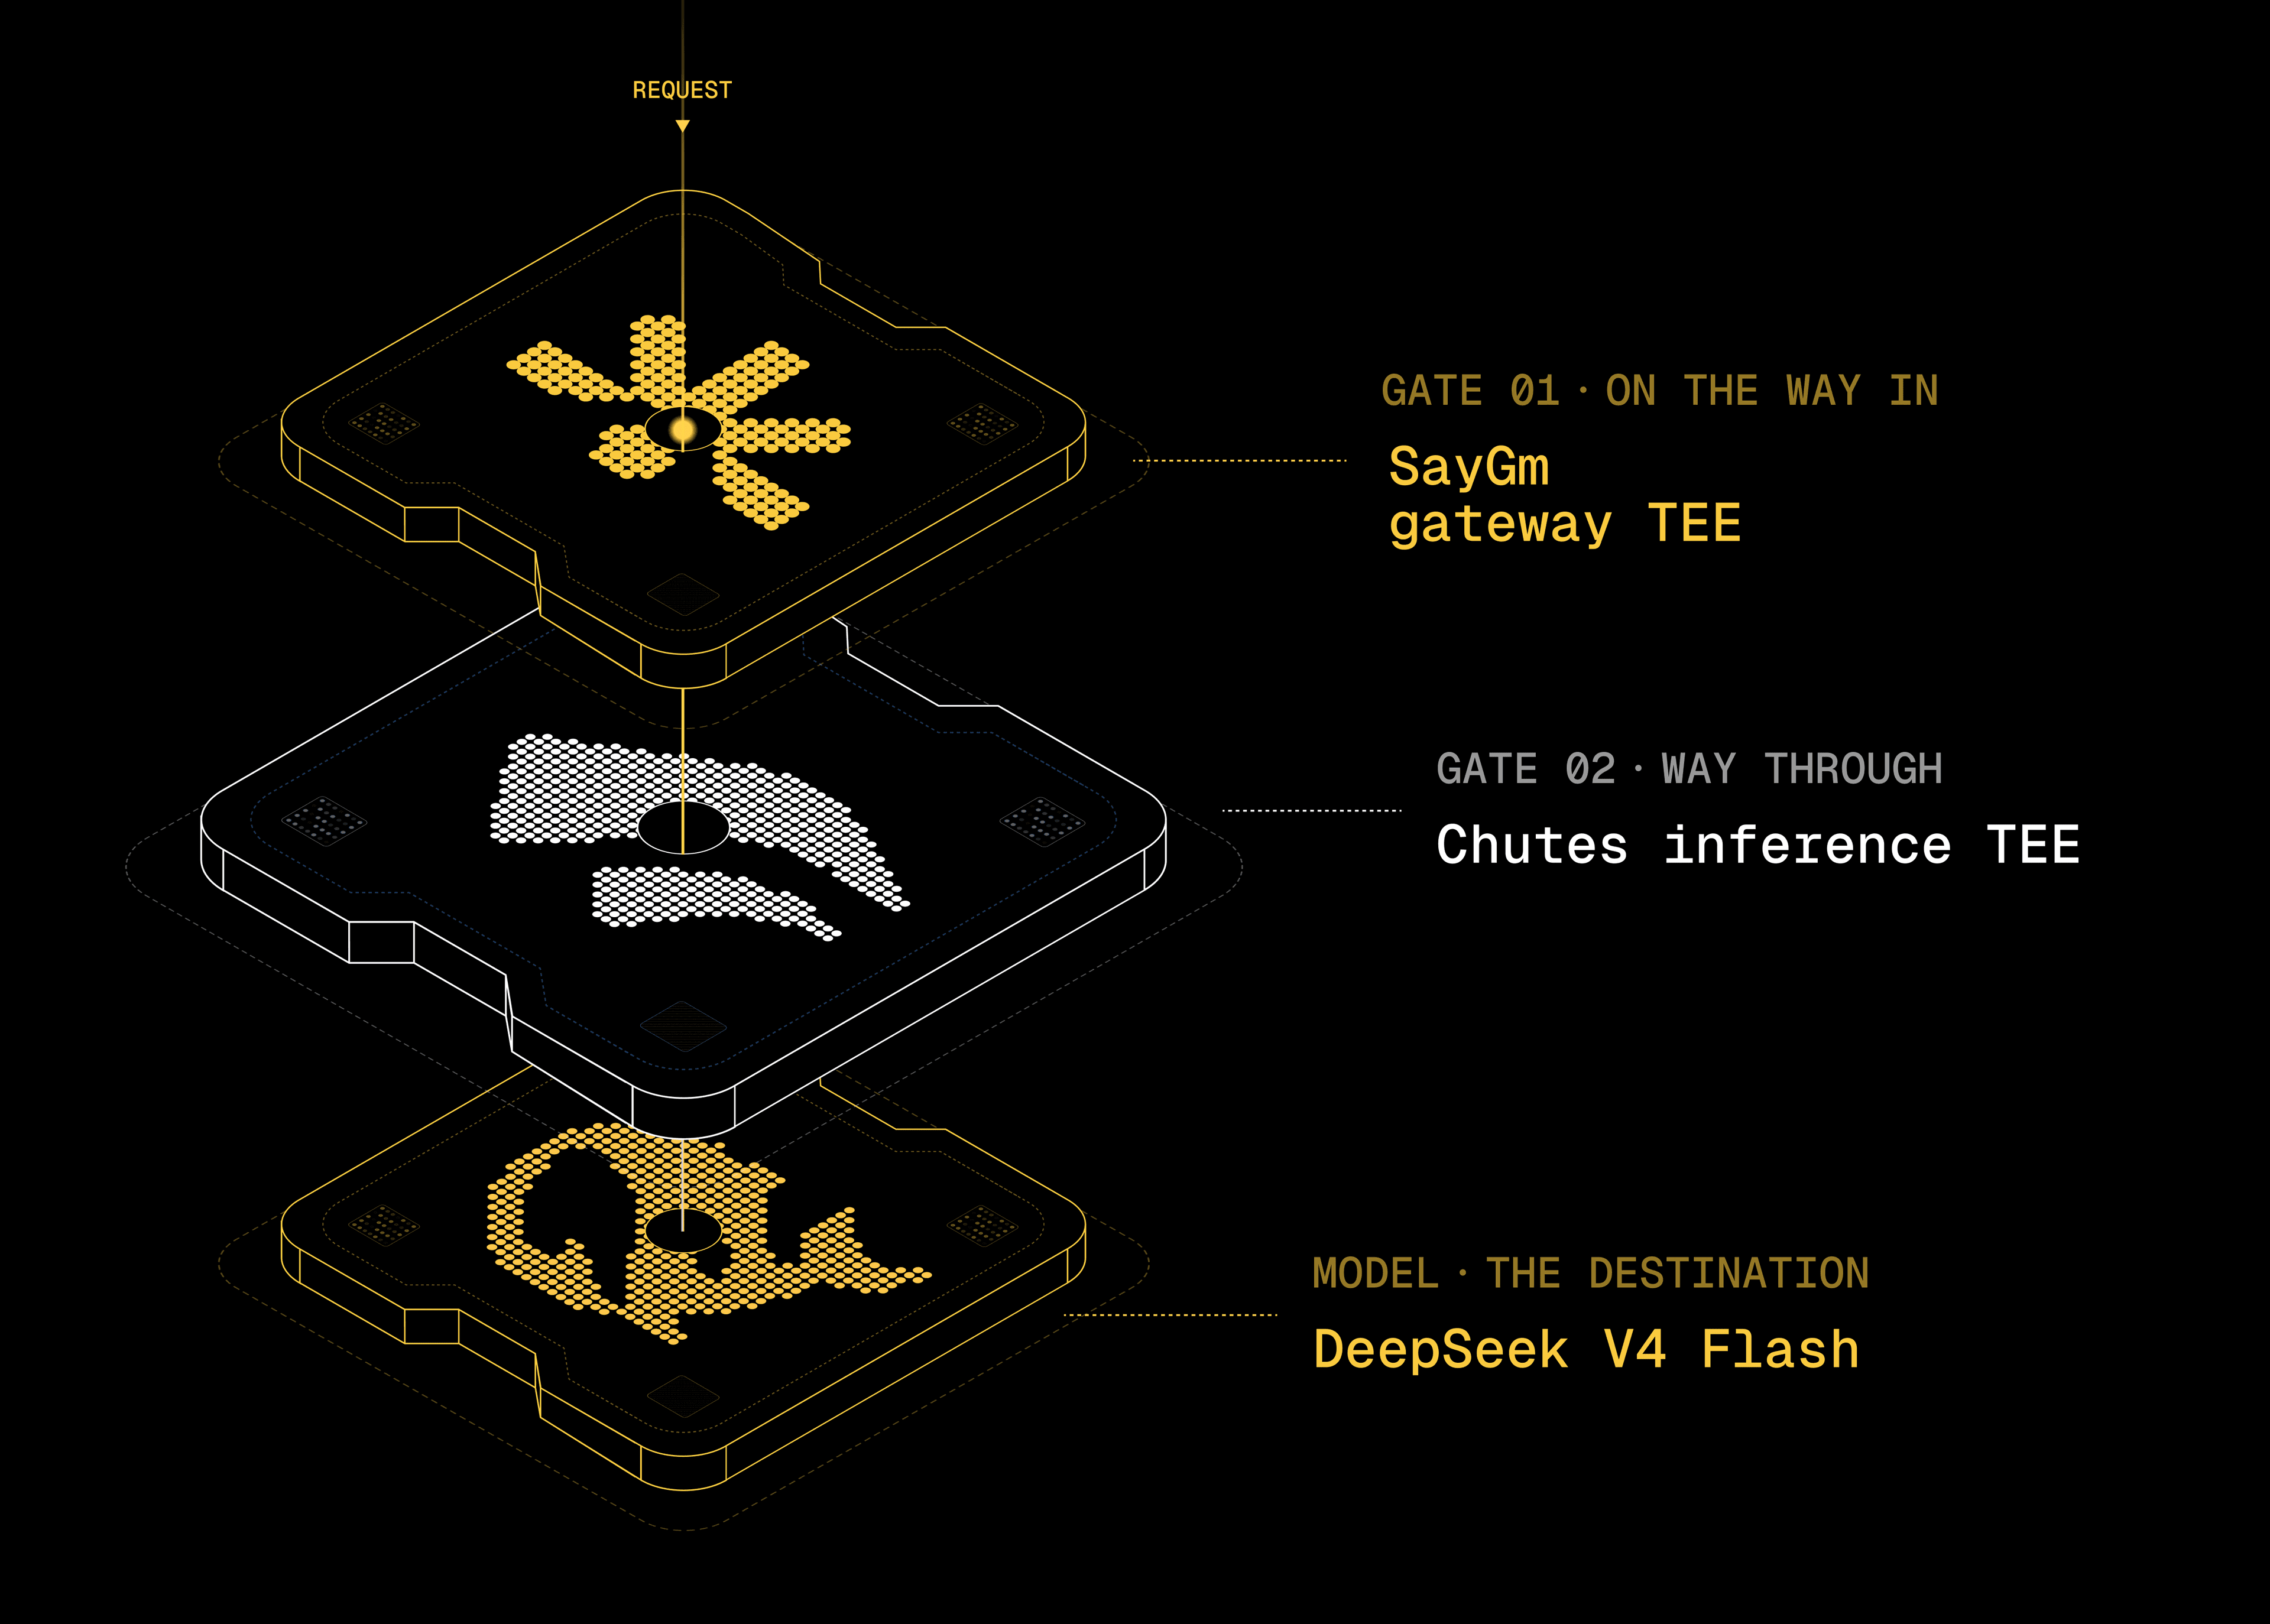
A request to a Chutes-served model moves like this:
- Your app calls SayGM. The request enters SayGM's gateway, which runs inside an Intel TDX confidential VM.
- The gateway picks an inference provider that has capacity for that model.
- The inference provider forwards the request to Chutes.
- Chutes runs inference inside its own TEE and the response streams back along the same path.
Inference providers compete for traffic by setting their own discount against retail pricing, which you can watch live on the miners page. That means the price of a Chutes-served model on SayGM is shaped by competition rather than a fixed reseller margin.
Which Privacy Tier Do Chutes Models Sit In?
Every model in the SayGM catalog carries a tier, and models routed to Chutes sit in the confidential tier. You can spot them by the -tee suffix on the model ID.
The confidential tier is reserved for open weight models served inside a trusted execution environment (TEE), where inference stays sealed from the moment the request arrives to the moment the response leaves. Our privacy documentation sets out exactly what each tier guarantees.
Chutes earns that label because it runs its own confidential compute stack. Intel TDX encrypts memory with keys only the CPU holds, NVIDIA's protected PCIe encrypts the channel between CPU and GPU, and every deployment is checked through remote attestation before it's allowed to serve traffic, as described in Chutes' write-up on verifiable privacy. The GPU operators running Chutes' hardware can't read the prompts passing through it.
That means your prompt is protected twice. SayGM seals it on the way in, inside the gateway's TEE, and Chutes keeps it sealed while the model runs, inside its own attested hardware. Each layer is checked on its own terms, so neither one is asking you to trust the other's word. That's what lets the confidential tier mean something: the privacy comes from two pieces of hardware you can verify, not from a promise on a website.
Choosing Chutes as Your Provider
Most of the time you don't need to think about providers. SayGM's default routing balances price, speed and reliability across everyone serving a model. But if you want a request served by Chutes specifically, the X-GM-Providers header handles it.
curl https://api.saygm.com/v1/chat/completions \
  -H "Authorization: Bearer $SAYGM_API_KEY" \
  -H "Content-Type: application/json" \
  -H "X-GM-Providers: chutes" \
  -d '{
    "model": "<model-id-from-catalog>",
    "messages": [{"role": "user", "content": "gm"}]
  }'
The header takes a comma-separated list, so chutes,kubetee lets SayGM choose between those two and nothing else. For every other way to control routing, see the full list of options in the routing docs.
Common Questions
Is Chutes AI safe for sensitive data?
Chutes models on SayGM sit in the confidential tier, so inference runs inside Chutes' hardware-attested TEE and your prompt isn't visible to SayGM or to the GPU operators serving it. When a customer or auditor asks where their data goes, the model's tier value in the catalog gives you a concrete answer.
Do I need to create a Chutes API key?
Not to use Chutes through SayGM. Your SayGM API key is all you need, and the connection to Chutes is handled on SayGM's side. If you want to call the Chutes API directly, you'll need an account and key from Chutes itself.
Get Started
Chutes on SayGM gives builders a direct line between two Bittensor subnets: SN64's TEE-protected open-weight models, delivered through SN28's confidential gateway, on the same base URL and key you already use.
To try it, create a SayGM API key, list the available models with GET /v1/models, and send your first request with X-GM-Providers: chutes.
About SayGM
SayGM is a drop-in inference gateway for teams who don't want to just take a company's word that their prompts are private. Every request is routed through a hardware-verified confidential environment - not even SayGM can see what's inside it. That's not a policy, it's provable. Swap in your existing OpenAI, Anthropic, or Gemini code and you're covered in minutes, at transparent, published rates with no hidden markup.
Say gm to AI at saygm.com.
Website | Twitter | Discord | Blog | Medium | Docs | LinkedIn
- AI
- Inference
- Privacy
BS